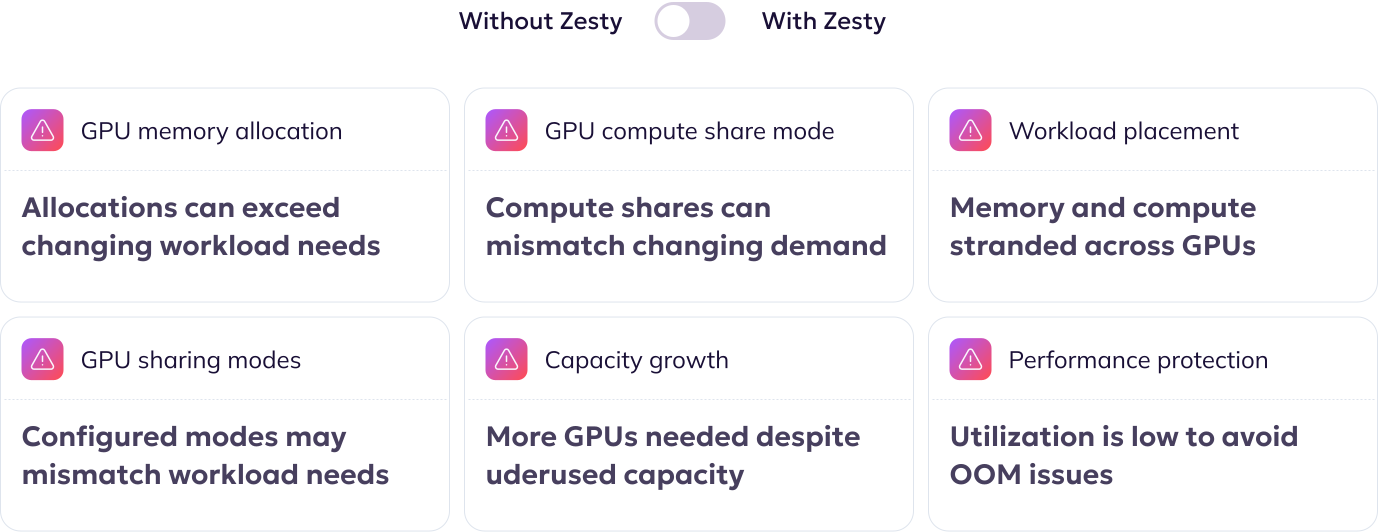
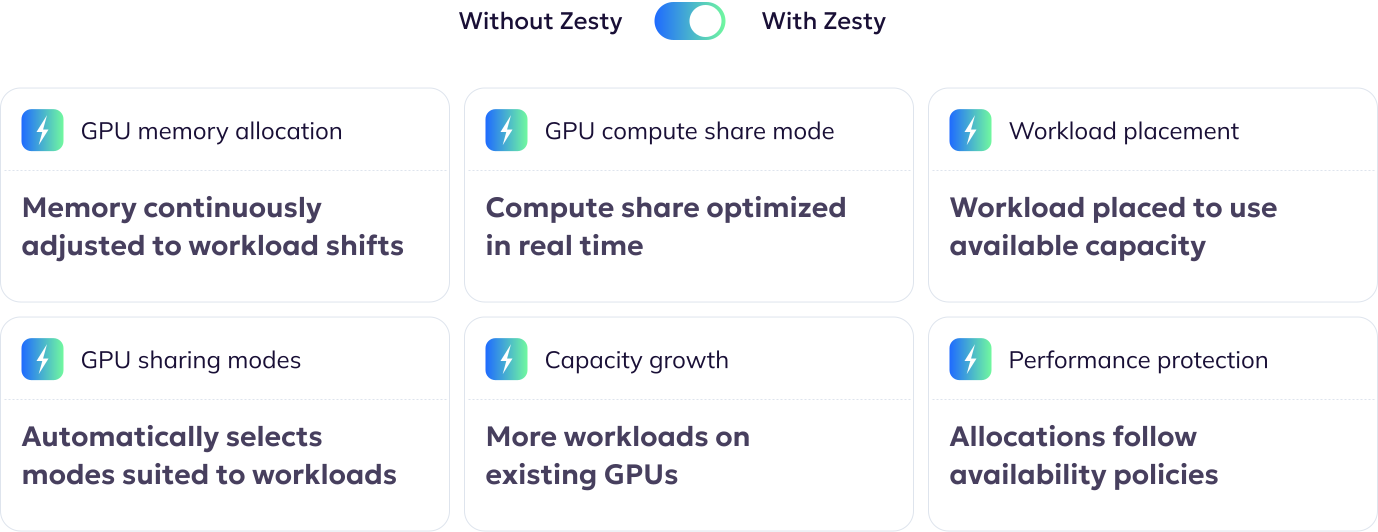
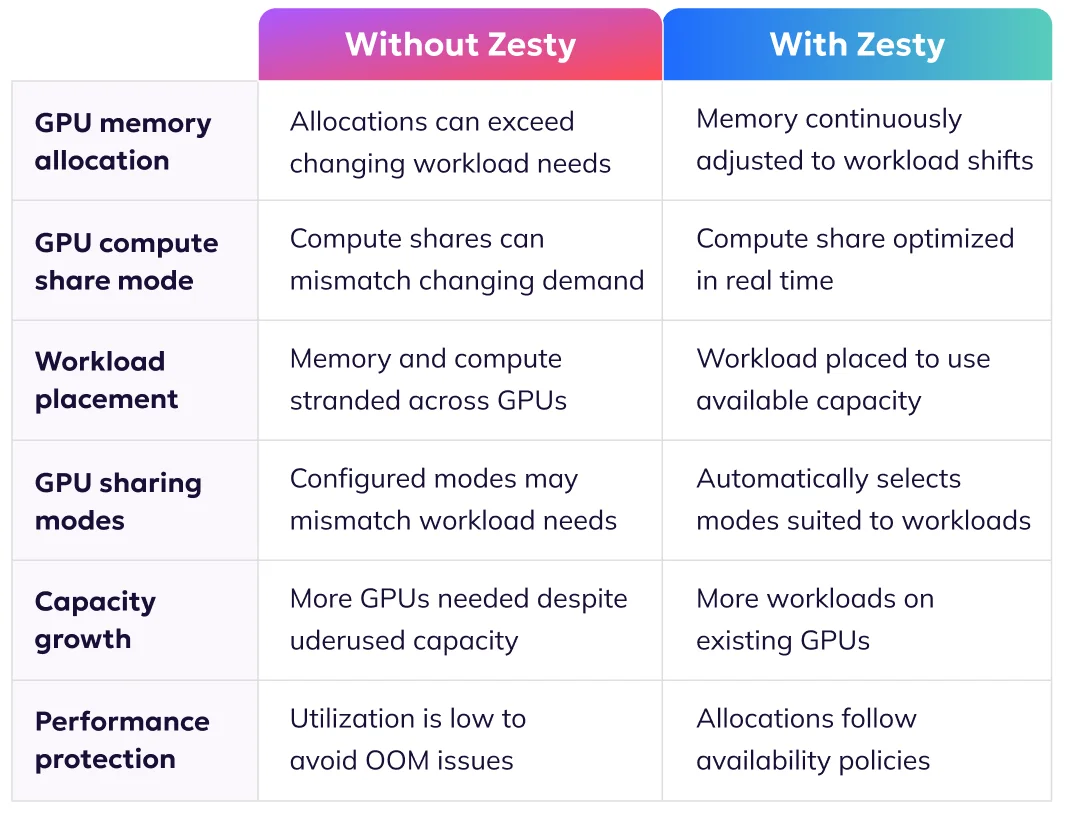
Automatically optimize GPU allocation and workload placement as AI workload demand changes. Run more workloads on existing GPUs within your performance policies and guardrails.
Increase GPU utilization with real-time automation
Optimize GPU allocations
in real time
Automatically adjust GPU memory allocation, compute share, and sharing mode as AI workload requirements change.
Optimize workload placement and density
Determine where workloads should run and how many can share each GPU based on their performance requirements, reducing stranded capacity while maintaining stability.
Works with your existing GPU setup
Zesty works with NVIDIA’s CUDA-native GPU fractioning, time-slicing, MPS, and Kubernetes schedulers such as KAI Scheduler. No application code changes, model changes, or manual edits to Kubernetes manifests are required.